Google Cloud and NVIDIA Announce General Availability of NVIDIA Vera Rubin Infrastructure
Oct 21, 2026, 3:45 AM · NVIDIA Blog
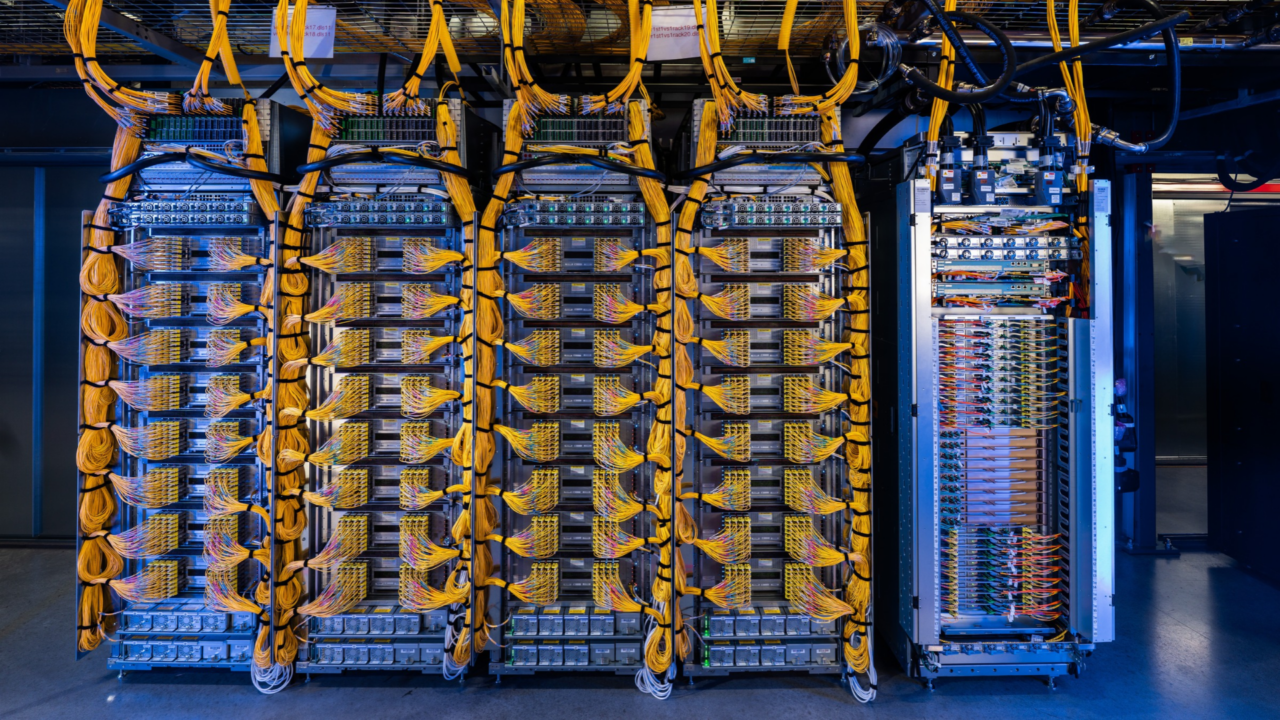
Google Cloud's A5X instances put Vera Rubin racks in reach of rented customers next month, and the first tenant is telling: a lab betting everything on reinforcement learning from experience.
Why it matters
Google Cloud and NVIDIA say A5X instances built on Vera Rubin NVL72 reach general availability next month, with Europe planned after that. The pitch is one integrated system for training, inference and large-scale reinforcement learning, and Google says it plans to scale this Vera Rubin build-out to as many as 960,000 Rubin GPUs across multiple sites.
That matters because the frontier's newest compute hunger isn't just bigger pretraining runs. It's the loop where agents generate experience, get graded and update. Whoever rents that loop cheaply and reliably shapes which labs can compete without owning a data center.
From the desk
We read this as the cloud catching up to where research is heading. The first customer named is Ineffable Intelligence, the London company founded by AlphaGo creator David Silver, which is using A5X to chase what it calls "superlearner" systems that learn continuously from experience. That's a meaningful signal. Reinforcement learning at scale needs fast trips between generating experience and training on it, and NVIDIA's argument is that Vera Rubin's CPU-to-GPU and in-rack bandwidth is built for exactly that cycle.
I'm genuinely for this kind of capacity reaching rentable cloud form. A research lab shouldn't have to raise for its own power plant to test a new learning paradigm. Renting the rack levels the field somewhat, and Europe getting access later is good for a region that keeps saying it wants to produce AI, not just consume it.
The WPP example is the part I'd hold more loosely. WPP says workloads that typically needed a multi-node cluster ran on a single A5X instance in initial tests, with creative agents producing video, upscaling and restyling under governed OpenShell sandboxes and human approval before execution. Human sign-off before an agent acts on brand assets is the right default. But "initial tests" from a vendor blog is not a production benchmark, and we'll want to see real throughput and cost numbers before calling it a consolidation story.
The confidential computing piece may age the best. Google says it will be among the first clouds offering NVIDIA Confidential Computing at rack scale on bare-metal A4X Max instances, and is making it generally available on G4 VMs. As agents touch proprietary models and sensitive data on hardware the customer doesn't own, that protection stops being optional.
The downside is scale itself. A plan reaching toward 960,000 GPUs is a power and concentration story as much as a compute story. The partners say they're exploring NVIDIA DSX MaxLPS to squeeze performance per watt within power budgets, which is an admission that electricity, not chips, is the binding constraint. If this becomes the norm, a small number of clouds and one chip vendor hold the keys to the next learning paradigm.
Context
A5X combines Vera Rubin NVL72 racks, ConnectX-9 SuperNICs, Google Cloud's Virgo Network and its fourth-generation liquid cooling, and slots into Google's AI Hypercomputer. The announcement was part of NVIDIA's European announcements around GTC Berlin. Customers named for Confidential G4 include Vertebrae, Polaris Cloud and Confidential Core AI.
Who feels it
- AI research labs
- Rack-scale Vera Rubin capacity for reinforcement learning becomes rentable rather than something labs must build themselves.
- Enterprises
- Confidential computing at rack scale and on G4 VMs gives regulated firms a clearer path to run sensitive agent workloads in the cloud.
- European customers
- Planned expansion to Europe could ease reliance on US-region capacity for frontier training and inference.
- Energy and grid planners
- A build-out aimed at as many as 960,000 GPUs puts more pressure on power budgets across multiple sites.
What to watch
- Whether A5X general availability lands next month as promised, and when European regions follow.
- Independent cost and throughput figures for A5X versus multi-node clusters, beyond WPP's initial tests.
- Results or papers from Ineffable Intelligence showing what experience-driven learning achieves at this scale.
- Uptake of rack-scale confidential computing among firms with proprietary models.