AI · Oct 21, 2026
OpenAI on Google Cloud lets companies spend Google commitments on GPT-6, and that changes procurementGPT-6 Astra Ultrafast on Blackwell claims up to 8x faster tokens, with OpenAI’s models tuning the kernels
· Updated · Signal Desk newsroom
Analysis of reporting by NVIDIA Blog. How we work
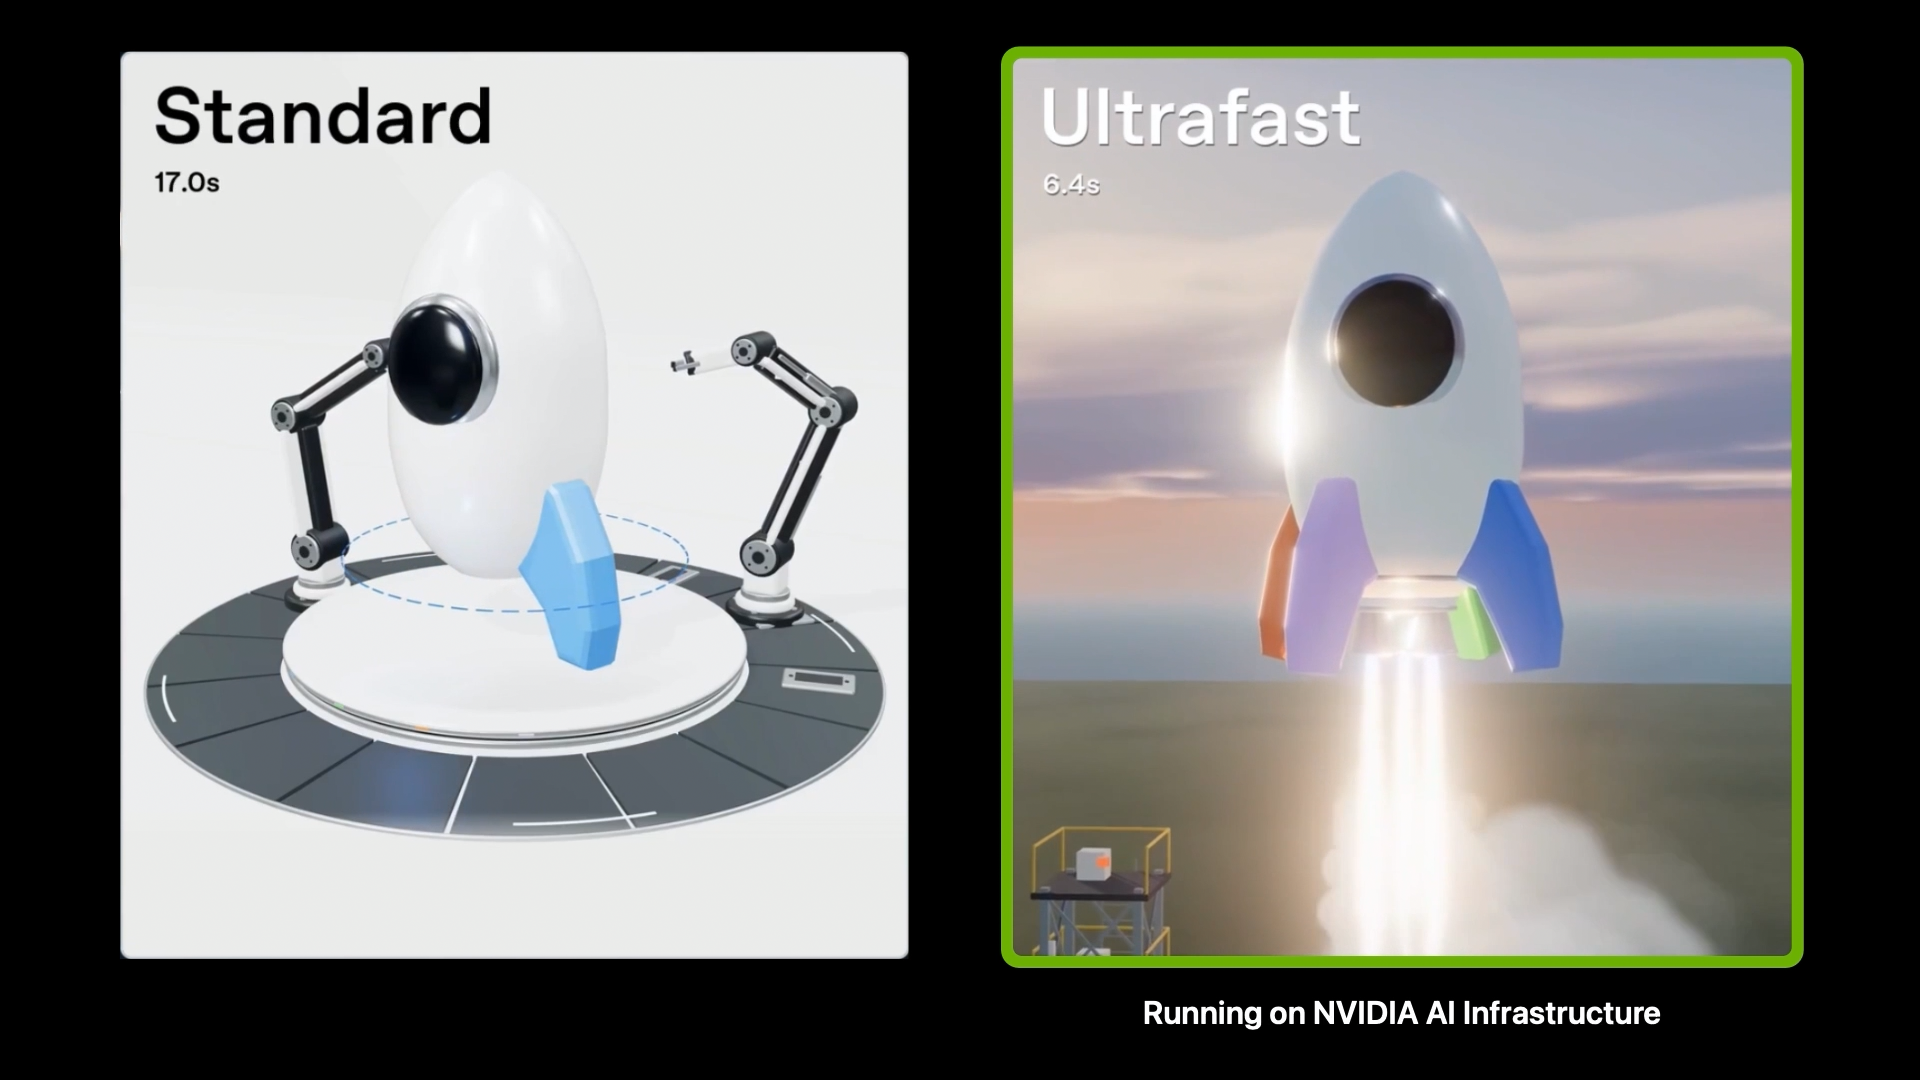
Nvidia says GPT-6 Astra Ultrafast is live in OpenAI’s API and for eligible ChatGPT Work and Codex users on Blackwell GPUs, claiming up to 8x faster token generation than Astra Standard. OpenAI says its own models helped write and optimize the inference kernels.
Key takeaways
- Astra Ultrafast is live in the API and for eligible ChatGPT Work and Codex users.
- Nvidia claims up to 8x faster token generation than Astra Standard.
- It targets code generation, tool use and interactive agent loops.
- OpenAI’s Philippe Tillet says models are good at programming Blackwell and Rubin GPUs.
- Compute CTO Uday Ruddarraju says internal models helped optimize inference.
What launched
Nvidia says GPT-6 Astra Ultrafast is live in the OpenAI API and for eligible ChatGPT Work and Codex users, running on Blackwell GPUs. It claims up to 8 times faster token generation than Astra Standard, aimed at code generation, tool use and interactive applications where agents iterate through edit-test-debug cycles. OpenAI’s GPT-6 guide covers when to use Fast and Ultrafast modes (GPT-6 guide).
OpenAI inference lead Philippe Tillet credits Nvidia tooling for making models “exceptionally good at programming Blackwell and Rubin GPUs,” with Astra turning that knowledge into high-performance kernels. Compute CTO Uday Ruddarraju says internal models helped optimize inference on Nvidia hardware.
Why speed matters for agents
When a coding agent waits on every tool call, latency determines whether a developer stays in flow. An 8x improvement, if it holds, matters most inside agent loops, which is why shipping it into the API, Work and Codex is the right place to test the claim. Customers have highlighted Astra’s speed in production (Higgsfield).
The figure is Nvidia’s and OpenAI’s, and independent latency measurements under multi-tenant load have not been published. Nvidia has been emphasizing performance per watt for agentic workloads across Blackwell and Vera Rubin (agentic performance).
Co-evolution and coupling
The deeper story is co-evolution: OpenAI’s models helping write kernels that serve OpenAI’s models on Nvidia silicon. That is impressive engineering and good utilization of deployed GPUs, treating performance as a continuing post-launch project rather than a single launch-day number. It also tightens the coupling between two companies with significant pricing power over the stack.
Pricing will determine impact. Faster tokens available only on top tiers shift the bottleneck from compute to cost. Ultrafast pricing and rate limits, independent latency tests and whether Work and Codex eligibility expands beyond early cohorts are the markers to follow. Latency is likely to become a standard marketing line across labs. More in our Nvidia coverage, OpenAI coverage and tools coverage.
Who feels it
- API and Codex developers
- Shorter agent cycles if access and pricing allow default use.
- Infrastructure buyers
- Strengthens Nvidia’s case and the value of programmable inference.
- Competitors
- Latency on agentic workloads becomes table stakes.
What to watch
- Ultrafast pricing and rate limits.
- Independent latency measurements against the 8x claim.
- Expansion of Work and Codex eligibility.
FAQ
What is Astra Ultrafast?
A faster serving mode for GPT-6 Astra running on Nvidia Blackwell GPUs.
How much faster is it?
Up to 8x faster token generation than Astra Standard, Nvidia claims.
Who can use it?
API customers and eligible ChatGPT Work and Codex users.
What role did OpenAI’s models play?
They helped write and optimize inference kernels, OpenAI says.
More on OpenAI
AI · Oct 14, 2026
White Circle says newer OpenAI and Google image models are easier to jailbreak than their predecessorsAI · Oct 19, 2026
Microsoft ships Guardian Agents, saying frontier models ‘can’t be trusted’AI · Oct 13, 2026
After months off the frontier, Google ships Gemini 4 Argon with benchmark claims and aggressive pricingAI · Sep 22, 2026
Opus 5.5 hands risky cyber prompts to an older Claude model, and that routing is the real launch story