More Performance From Every Byte: How Full-Stack Codesign Solves AI’s Memory Challenge
Nov 5, 2026, 8:00 AM · NVIDIA Blog
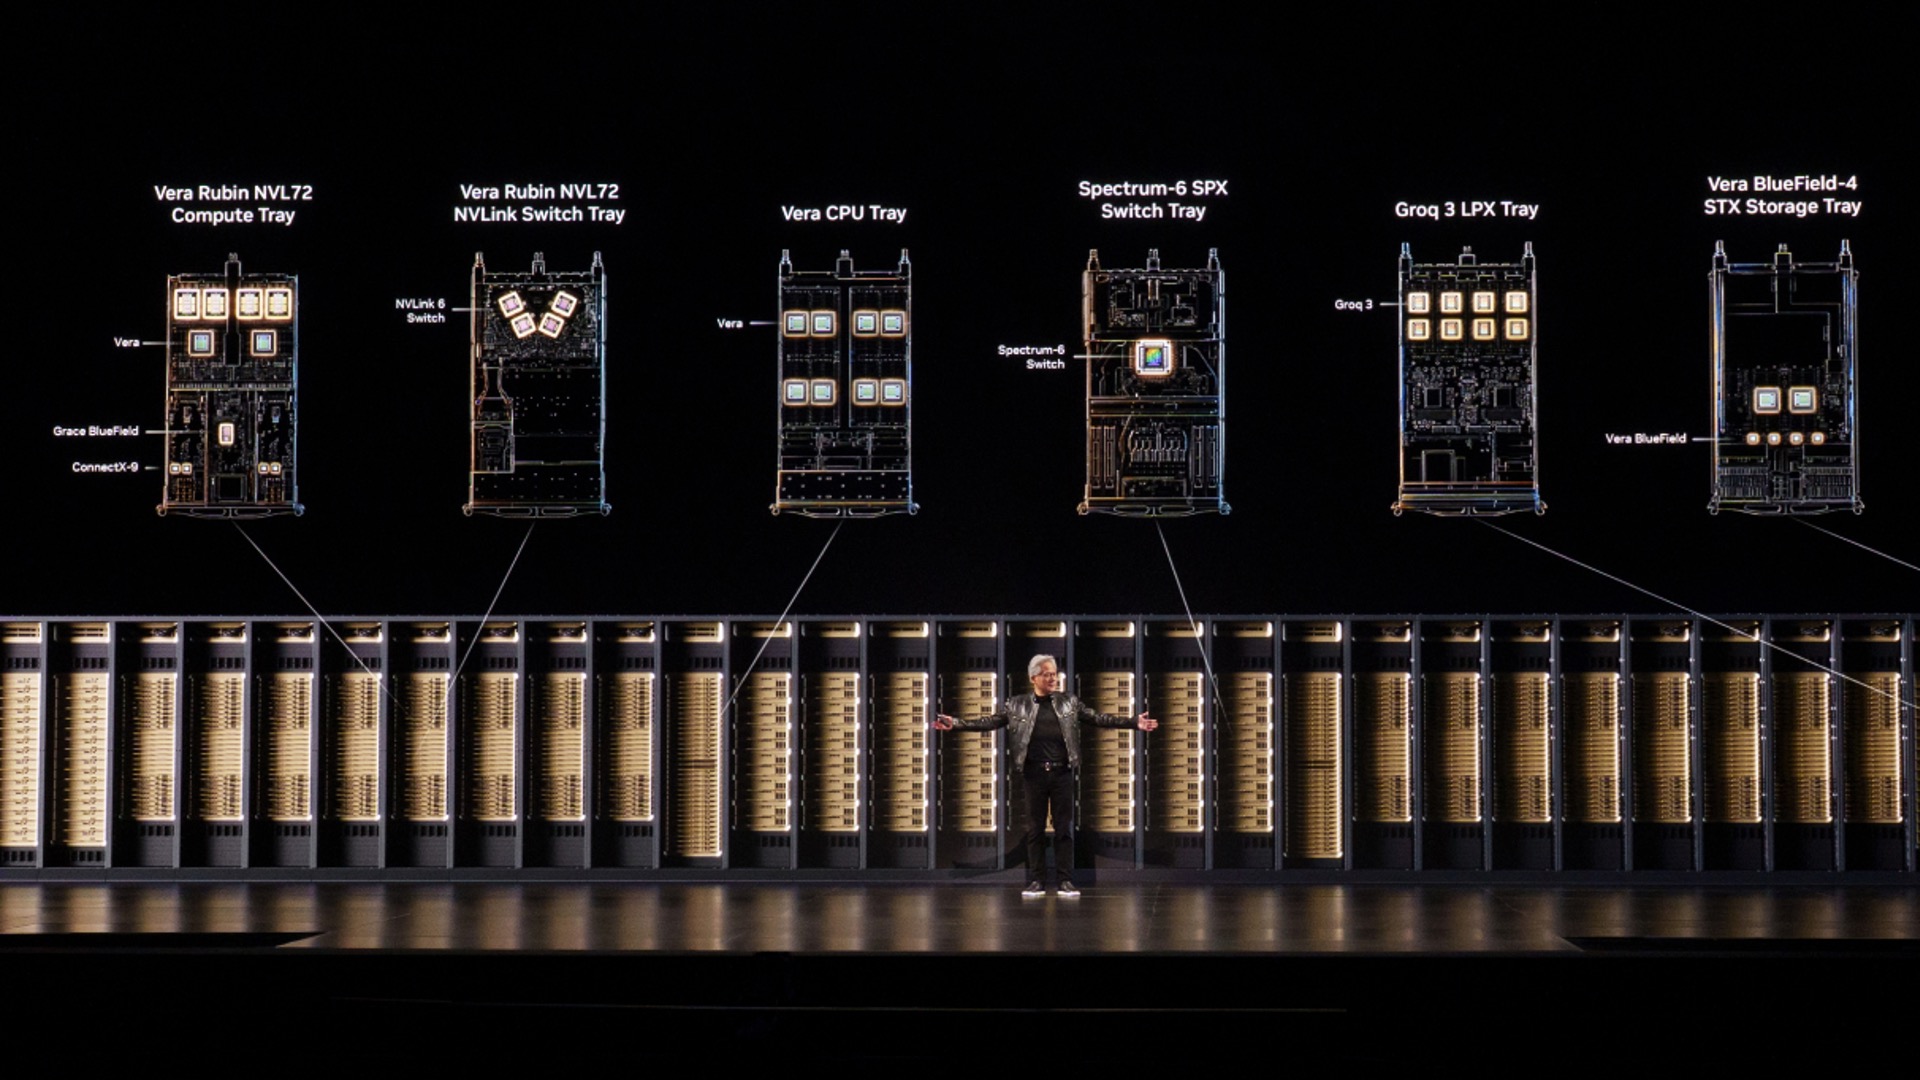
NVIDIA argues AI's memory crunch is solved less by packing HBM and more by codesigning GPUs, CPUs, networking, and software so every byte does more useful work.
Why it matters
Bigger models, longer contexts, and agentic trajectories are squeezing GPU high-bandwidth memory while supply stays tight. NVIDIA's answer is full-stack codesign: shrink what must live in HBM, park the rest on the right cheaper tier, and fetch it before it is needed.
From Blackwell Ultra to Vera Rubin, the company says HBM capacity per GPU rose roughly 3% while agentic throughput per dollar rose by up to 30× on SemiAnalysis AgentX. The hierarchy runs HBM for hot weights and KV cache, then CPU memory, local SSDs, and shared context storage.
If those ratios hold outside the slides, operators buy systems for tokens per watt, not GB of HBM brag.
From the desk
We're aligned with the warehouse-and-docks metaphor. Extra HBM without bandwidth and orchestration is empty aisle space that still draws power. Agentic inference makes it worse — KV cache that spans tool calls, RAG that grows prompts, parameters in the trillions competing for the same tier.
NVIDIA's toolkit is familiar if you follow the stack: NVFP4 to shrink weights and KV versus FP8, spreading weights across NVL72 so each GPU keeps more room for cache, Vera CPU plus NVLink-C2C as a nearby waiting room for paused context, Dynamo moving inactive KV to CMX shared context storage with partners from Cloudian to WEKA, and Nemotron Retriever plus cuVS keeping RAG indexes off HBM until passages are needed. KV Cache Reuse treats context as a system-wide resource.
I take vendor-chosen AgentX comparisons carefully and still think the direction is correct. AI factories should optimize useful tokens inside a power envelope. The downside if codesign becomes synonymous with one vendor's hierarchy: switching costs calcify and alternative memory architectures struggle to prove in. Useful efficiency is whatever delivers service-level tokens without lying about capacity. Measure goodput, not just installed HBM.
Context
NVIDIA cites first-mover adoption of HBM3e and HBM4 with partners, and lists recent NVFP4 model releases from Black Forest Labs, Thinking Machines, Reflection, Meta, StepFun, and Nemotron. GB300 versus H200 and Vera Rubin versus GB300 figures anchor the throughput-per-dollar claims.
Who feels it
- AI factory operators
- A playbook to squeeze more concurrent users from constrained HBM budgets.
- Model builders
- Incentive to ship NVFP4 and similar compact checkpoints.
- Storage partners
- Demand for CMX-class context tiers tuned for short-lived KV, not archival.
- Rival silicon vendors
- Pressure to publish hierarchy-aware efficiency, not only peak FLOPs.
What to watch
- Independent AgentX or equivalent reproductions of the 30× throughput-per-dollar claim.
- Customer deployments of Dynamo KV offload to CMX under production SLAs.
- HBM pricing and supply into 2027 as the constraint narrative holds or breaks.
- Whether NVFP4 becomes a default release format across major labs.
Companies: NVIDIA