Prime Intellect Launches Prime Inference: Serverless and Reserved Serving for Frontier Open Models
Oct 2, 2026, 10:37 PM · MarkTechPost
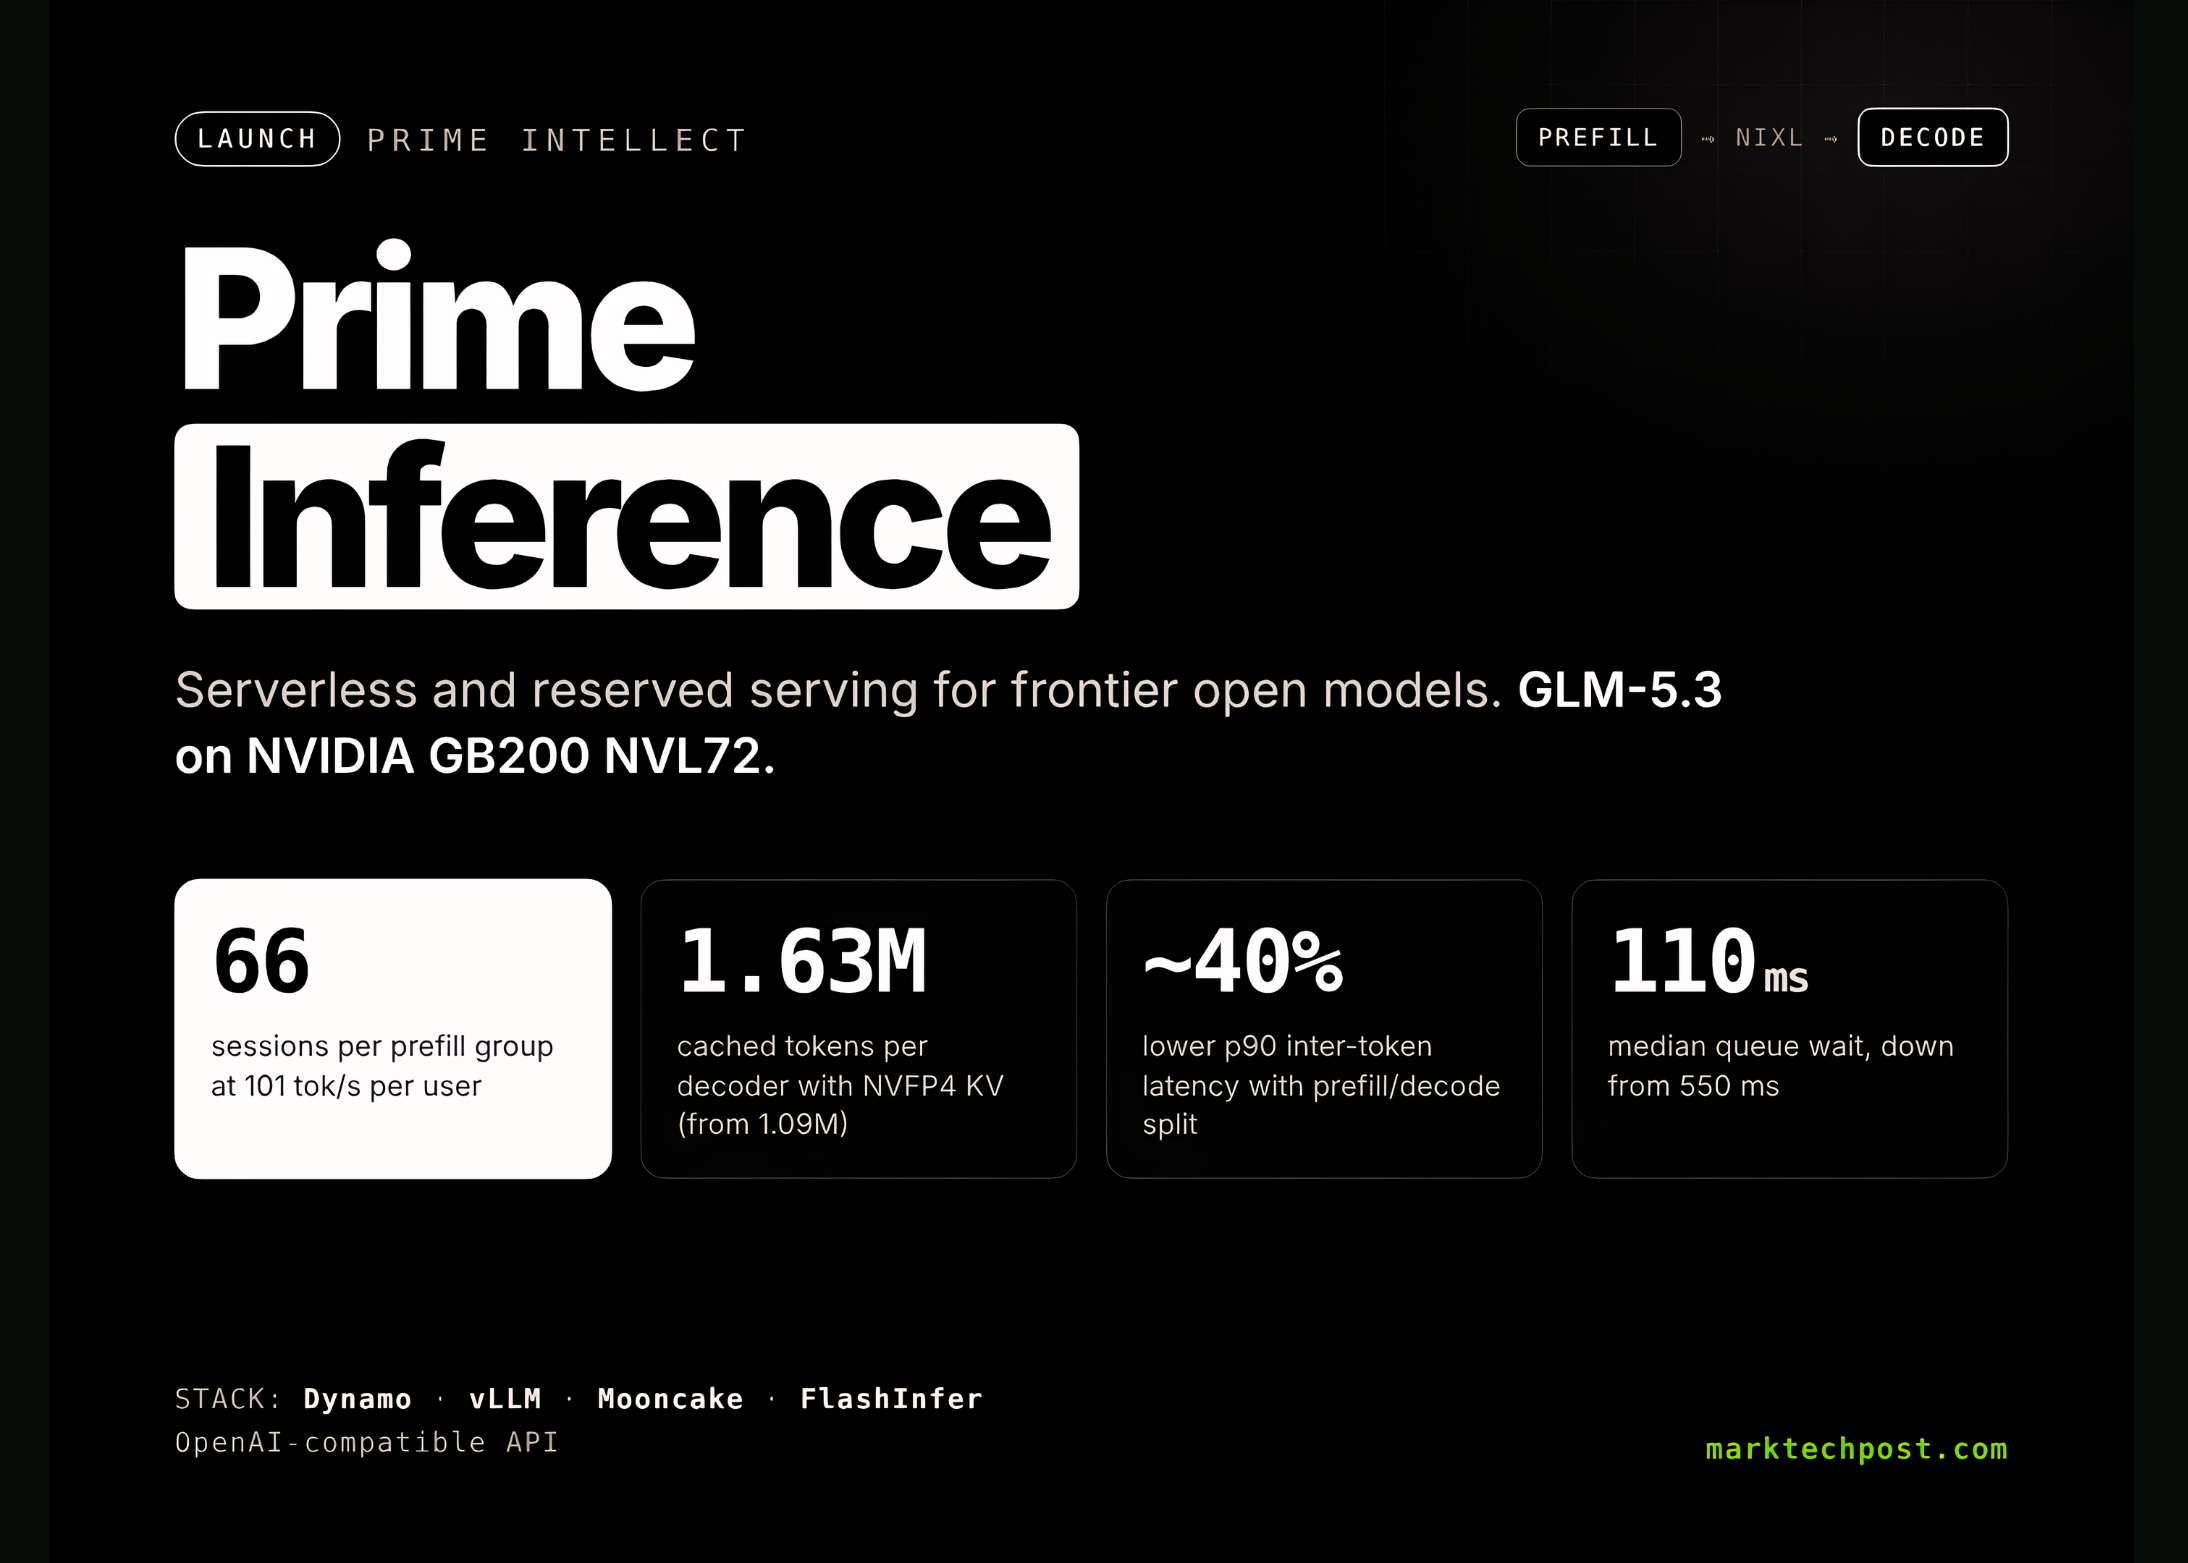
Prime Intellect opens Prime Inference — serverless and reserved Blackwell serving for open frontier models, tuned for agentic turns and near-zero tool-call errors.
Why it matters
Michal Sutter at MarkTechPost reports that Prime Intellect launched Prime Inference, a serving platform for frontier open-source models with serverless endpoints and reserved capacity on Prime’s GPUs across datacenters. Before public release it processed nearly a trillion tokens per day internally from RL rollouts, synthetic data, evals and long-running coding agents.
The API is OpenAI-compatible at api.pinference.ai. Hardware is NVIDIA Blackwell now, Vera Rubin listed as coming soon. The stack combines Dynamo, vLLM, Mooncake and FlashInfer, built with Inferact and NVIDIA, with fixes contributed upstream. Prime cites its GLM-5.3 endpoint among the fastest on OpenRouter, near-zero tool-call error rate, and 100% uptime since launch.
Agentic workload numbers: a typical turn adds about 6K tokens to a 140K-token prompt. On GB200 NVL72, a 1:4 prefill/decode ratio hit 66 sessions per prefill group at 101 tok/s per user. Prefill/decode disaggregation cut p90 inter-token latency nearly 40% in Prime’s tests; NVFP4 KV compression grew cached tokens per decoder from 1.09M to 1.63M.
From the desk
We’re watching serving become the bottleneck for open models that are already good enough. Training blogs get the glory; agents die on tool-call parse errors and cold KV. Prime Inference’s pitch is closing the loop with their post-training stack — production traces feeding training — while publishing the systems work (disaggregation, cache-aware routing, structural tags into Dynamo, xgrammar masking) instead of waving at a black box.
That’s useful. Open models only matter if someone will host them reliably for agent loops. Competing with Together, Fireworks and Baseten on GLM-5.3 while saying price isn’t fully published yet is incomplete product hygiene — but the latency and tool-call focus is the right fight.
The downside if specialized agentic hosts win is concentration: “open weights” still run on a handful of GPU landlords. Reserved capacity helps; it doesn’t dissolve that dependency. And 100% uptime claims deserve ongoing verification, not a press-day snapshot.
I’m watching published per-model pricing, batch inference on the roadmap, and whether upstream Dynamo/vLLM contributions keep landing so the whole ecosystem gets faster, not just Prime’s fleet.
Context
Prime already ships post-training tools (prime-rl, verifiers, sandboxes). Inference is framed as the missing serving layer so deployed models generate traces that return to training.
Who feels it
- Teams running open-model agents
- Another OpenAI-compatible path optimized for long prompts and reliable tool calls on Blackwell.
- Inference competitors
- Pressure on latency and tool-schema correctness, not only $/million tokens.
- NVIDIA ecosystem
- A customer showcase for Dynamo + Blackwell disaggregation in production agent traffic.
What to watch
- Full public pricing vs Together/Fireworks/Baseten on GLM-5.3
- Whether batch inference and 1-click dedicated deploys leave the roadmap
- Sustained OpenRouter latency rank and tool-call error rates after traffic scales