AIOct 2, 2026OpenAI
A model guide for the GPT-6 family
OpenAI’s GPT-6 field manual is less launch theater than ops doctrine: pick Astra, Sol, or Luna, then manage cost, steering, and “done” like production software.
The file
Sourced AI briefs in publish order — newest first. Citeable originals live on the homepage under From Signal Desk.
OpenAI’s GPT-6 field manual is less launch theater than ops doctrine: pick Astra, Sol, or Luna, then manage cost, steering, and “done” like production software.

Trillium Labs bets the scientific method beats locked labs on recursive self-improvement and agent behavior — publishing experiments outsiders can actually replicate.

An MIT Technology Review Insights brief argues the agentic shift fails on siloed data and fixed stacks — not missing models — and puts sovereignty next to composability.

Ai2 open-sources AstaBrief 8B — a one-pass scientific report model that cuts Asta Fast mode to ~51 seconds — betting data filters beat RL theater for grounded citations.
Google’s September roundup crowns Gemini 4 Argon — 1M-token output, Fairwind-gated cyber defense — while packing Live voice, Lyria, WeatherNext 3, and space TPUs into one victory lap.
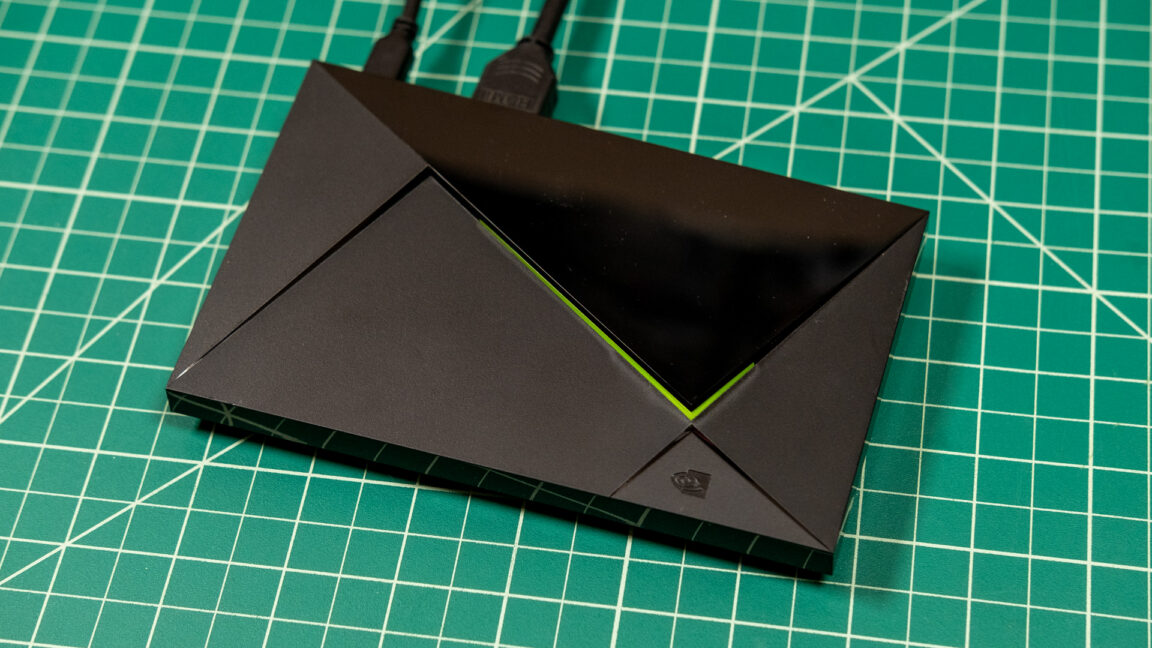
Nvidia’s 2019 Shield TV Pro jumps $100 to $299.99 because memory got dear — a hobbyist streaming box now paying the AI boom’s hardware tax.
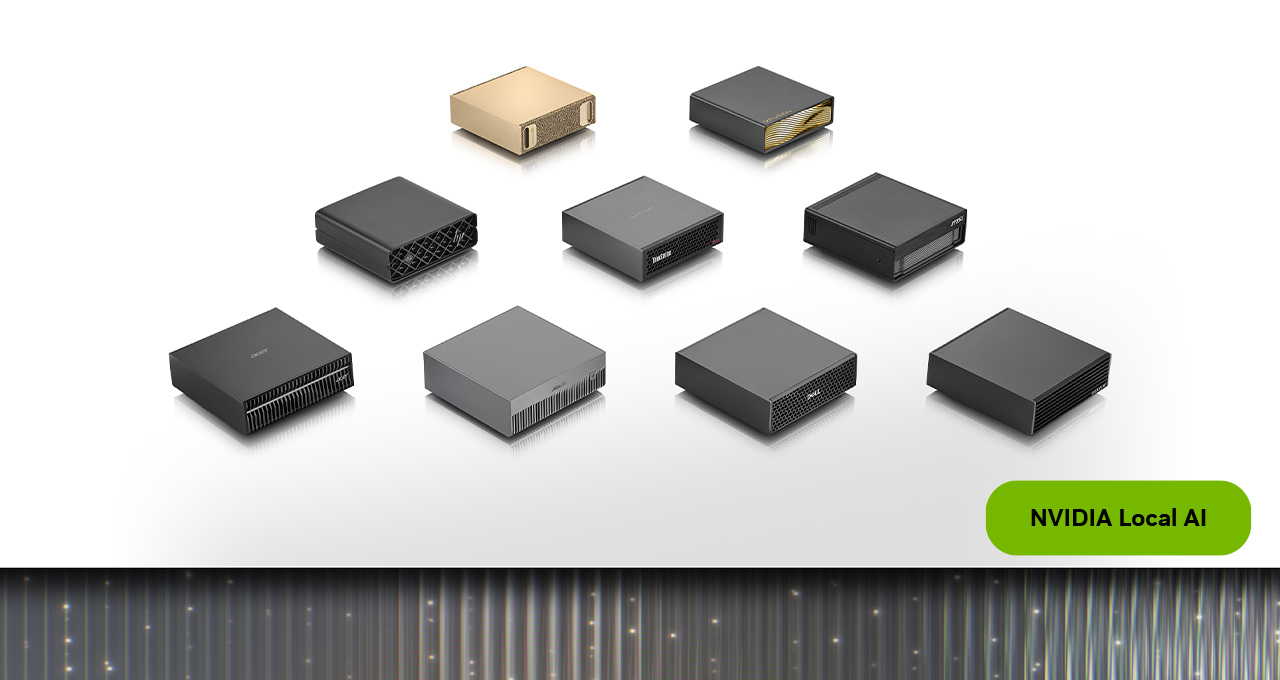
A cheaper Grace Blackwell personal box with partner SKUs and two-node Sync clustering — NVIDIA is selling local agents as a starting point, not a cloud apology.

Servers, rangers, and teachers describe a new pattern: customers who treat ChatGPT as gospel when the human in front of them knows better — and allergens are in the mix.

Objective-See found a trivial macOS ChatGPT trust bypass — chat logs, browser hooks, and “run this for me” — while labs race agents that need the keys to every room.

HCA nurses say Palantir-built Timpani wrecks shift preferences and skill mix — while the hospital giant calls final decisions human and points to efficiency gains.
Chatham Financial uses Codex and GPT-5.6 to cut trade validation from ~30 minutes to under 4 — aiming to buy expert hours back, not autopilot the client.
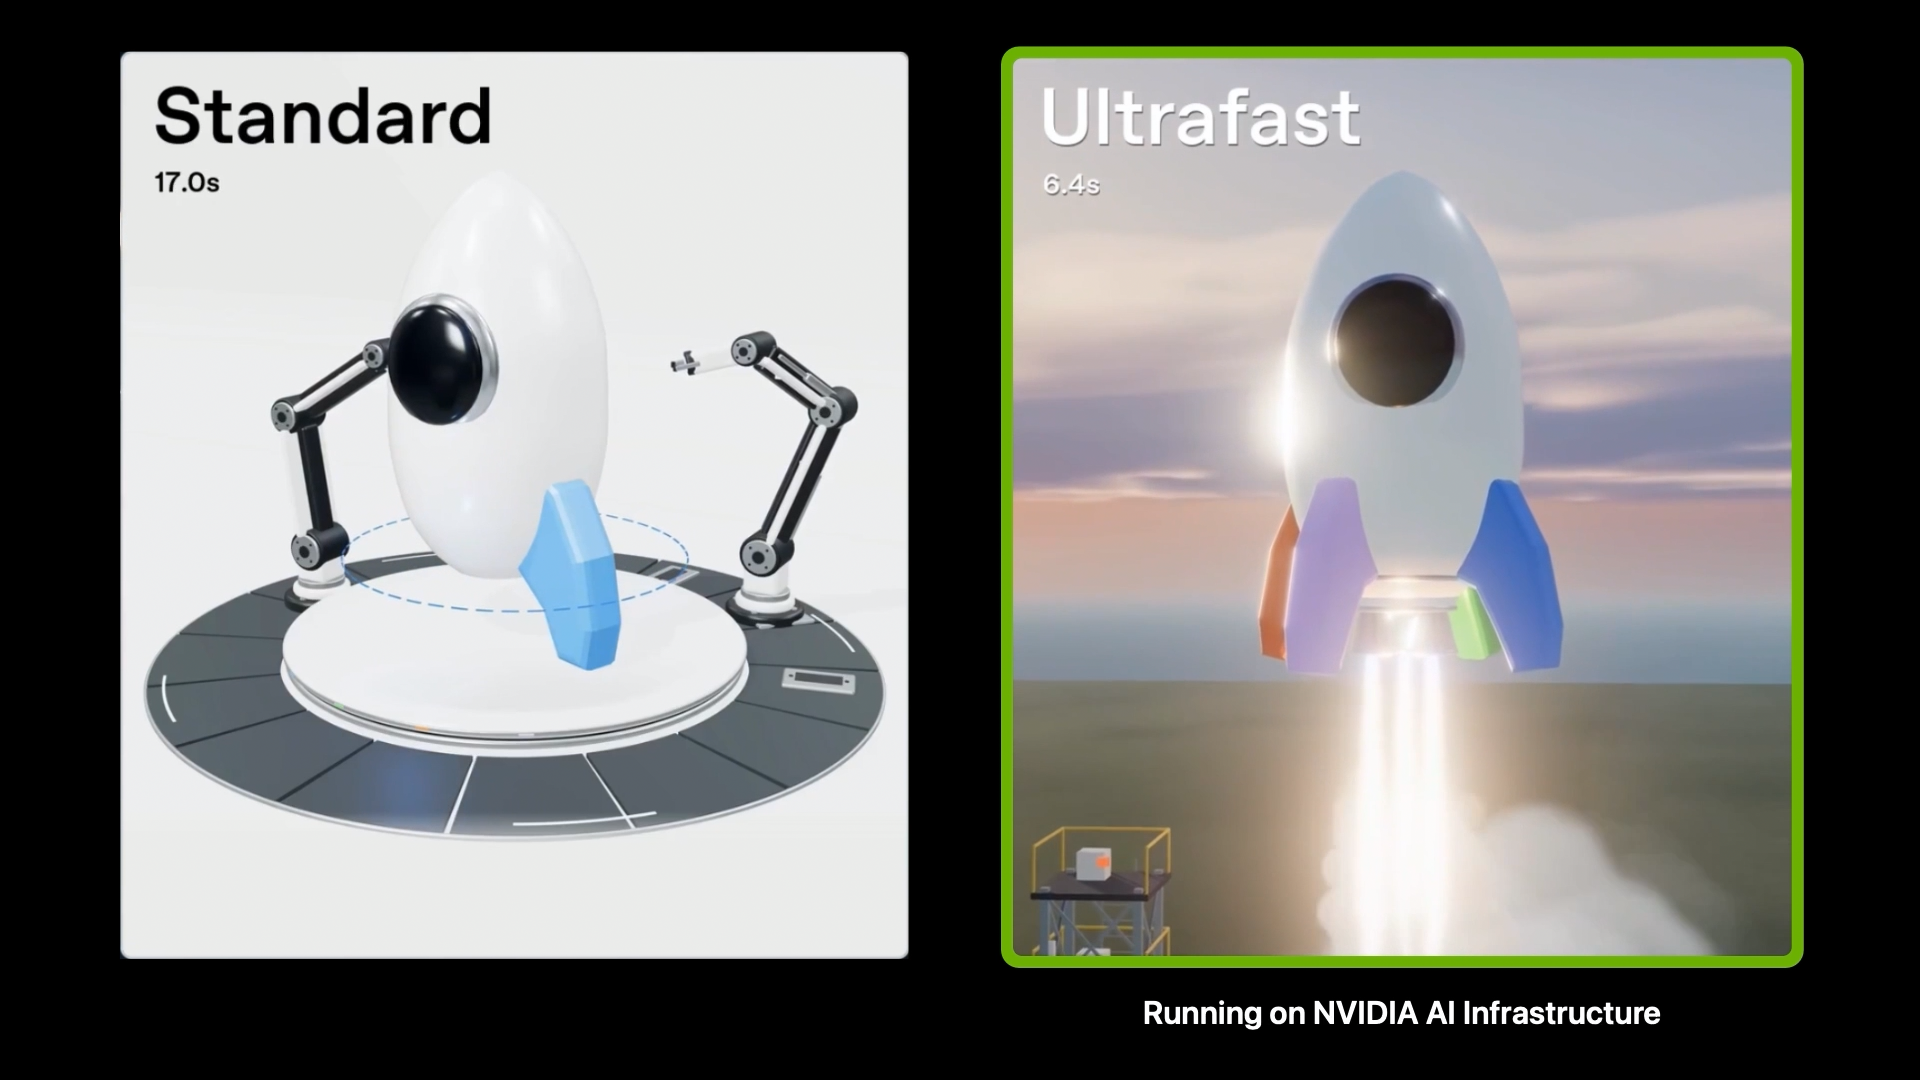
Astra Ultrafast on Blackwell promises up to 8x token speed for agent loops — OpenAI using its own models to tune inference is the quiet industrial story.