NVIDIA cuDSS Now Generally Available to Accelerate Engineering and Scientific Simulations
Oct 21, 2026, 3:30 AM · NVIDIA Blog
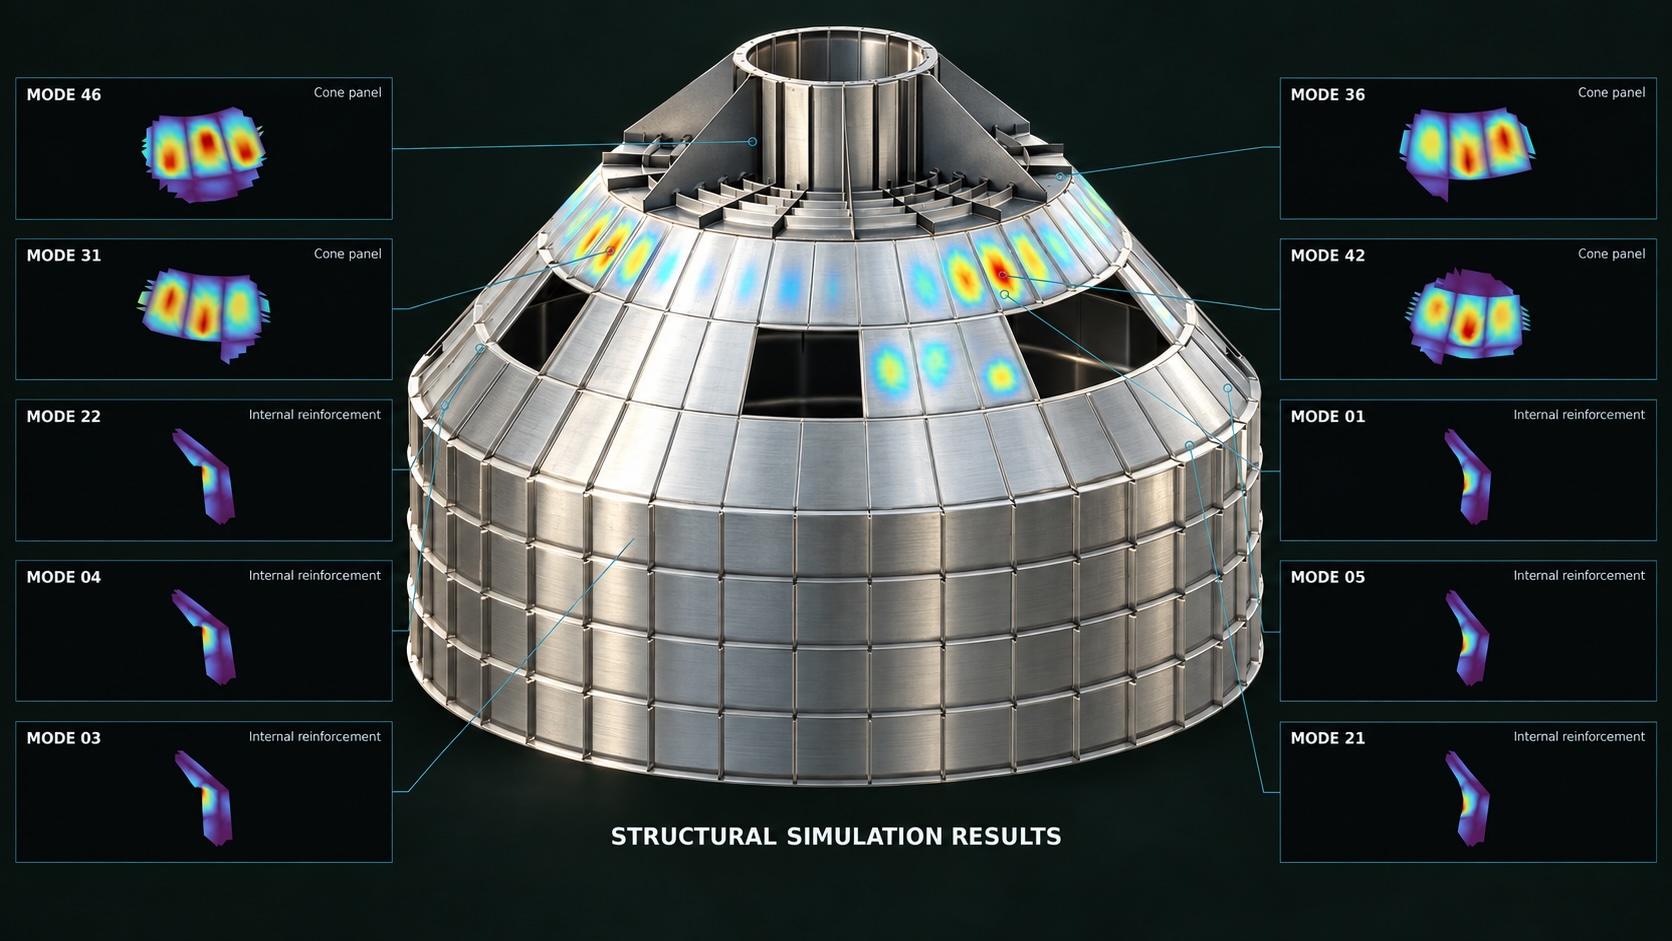
The least flashy NVIDIA news from Berlin may have the longest tail: a GPU library for the sparse math that throttles chip, aircraft and materials simulations is now generally available.
Why it matters
NVIDIA made cuDSS generally available. It is a CUDA-X library that moves the solving of large sparse linear systems, a step that repeats over and over inside engineering simulations, from CPUs onto GPUs. It works through C, C++, Python and Fortran, and NVIDIA says it scales from a single workstation to clusters.
The partner list is the real signal. Applied Materials reports up to 10x faster sparse solves versus CPU-only in its Ginestra platform. Dassault Systèmes reports 8x to 10x in Abaqus and its electromagnetic solvers. ZEISS SMT, using COMSOL, measured a 4x speedup on an EUV lithography plasma simulation that still took six days and 14 hours end to end. Cadence, Siemens and Synopsys are building it into their tools too.
When the incumbents of simulation software adopt a library, engineers get it without changing how they work. That is how compute shifts actually happen.
From the desk
We like this one because it is AI-era hardware being pointed at something unambiguously useful. Faster sparse solves mean more design iterations per week for chips, structures and devices. If a team can test more ideas before cutting metal or taping out silicon, products get better and waste goes down. No chatbot required.
The ZEISS figure is a useful reality check. A 4x speedup that still leaves a run at well over six days tells you how heavy these workloads are, and why the sparse solver is a choke point worth attacking. It also tells you GPU acceleration is not magic; it moves the wall, it does not remove it.
The caveats are the usual ones for vendor announcements. These are partner-reported numbers, framed against CPU-only baselines, on unspecified hardware configurations. Up to 10x is a ceiling, not an average. We would want to see how the gains hold on the messy, ill-conditioned problems engineers actually run, and how much of the total simulation time the solver represents once everything else is counted.
The longer-term story is about leverage. Applied Materials, Cadence, Synopsys and the lithography supply chain are all using NVIDIA GPUs to design the next generation of semiconductors and the tools that make them. That is a virtuous loop for engineering speed. It is also another layer of dependence on one vendor's software stack, sitting underneath the simulation packages that whole industries rely on. A sparse solver that only runs well on NVIDIA hardware makes switching costs quietly higher.
Our read: good for engineers, good for NVIDIA, and worth noticing by anyone who cares about how concentrated the industrial compute stack is becoming.
Context
Sparse linear systems show up whenever a simulation breaks a physical object into a mesh, as in finite element and multiphysics methods. Most of the matrix entries are zero, which makes them hard to accelerate efficiently. The announcement was part of NVIDIA's GTC Berlin slate.
Who feels it
- Simulation engineers
- Speedups arrive inside familiar tools like Abaqus, COMSOL and STAR-CCM+, so more design iterations without new workflows.
- Semiconductor industry
- Chip, device and lithography modeling is the headline use case, tightening the loop between GPU makers and chip designers.
- Software vendors
- Integrating cuDSS becomes a competitive checkbox for simulation packages that have not yet done it.
- CPU and rival accelerator makers
- A core HPC workload moves toward NVIDIA's software ecosystem, raising the bar for alternatives.
What to watch
- Independent benchmarks of cuDSS on difficult real-world sparse problems
- Pricing and licensing of GPU-accelerated tiers in the partner simulation packages
- Whether open-source solvers or rival accelerators close the gap
- End-to-end time savings reported by customers, not just solver speedups
Companies: NVIDIA