Simplifying Model Serving Across Multiple GPUs with NVIDIA TensorRT Multi-Device Integration in NVIDIA Dynamo-Triton
Dynamo-Triton can now own a multi-GPU TensorRT plan behind one gRPC call — latency drops hard, but you’re trading silicon for speed.
The file
Sourced AI briefs in publish order — newest first. Citeable originals live on the homepage under From Signal Desk.

Dynamo-Triton can now own a multi-GPU TensorRT plan behind one gRPC call — latency drops hard, but you’re trading silicon for speed.
AWS’s Strands team open-sourced a full agent harness claiming 28% lower token cost at similar accuracy — the loop around the model is the product now.

NVIDIA’s eval guide says stop grading vibes and tool-call trivia — gate releases on whether the environment actually reached the goal state.

OpenAI set up a math advisory group at IAS after a Navier-Stokes splash — influence without a brake pedal on the research pace.

Apptopia’s early Muse numbers beat ChatGPT’s first 12 days on matched iOS turf — distribution muscle, not just model magic.

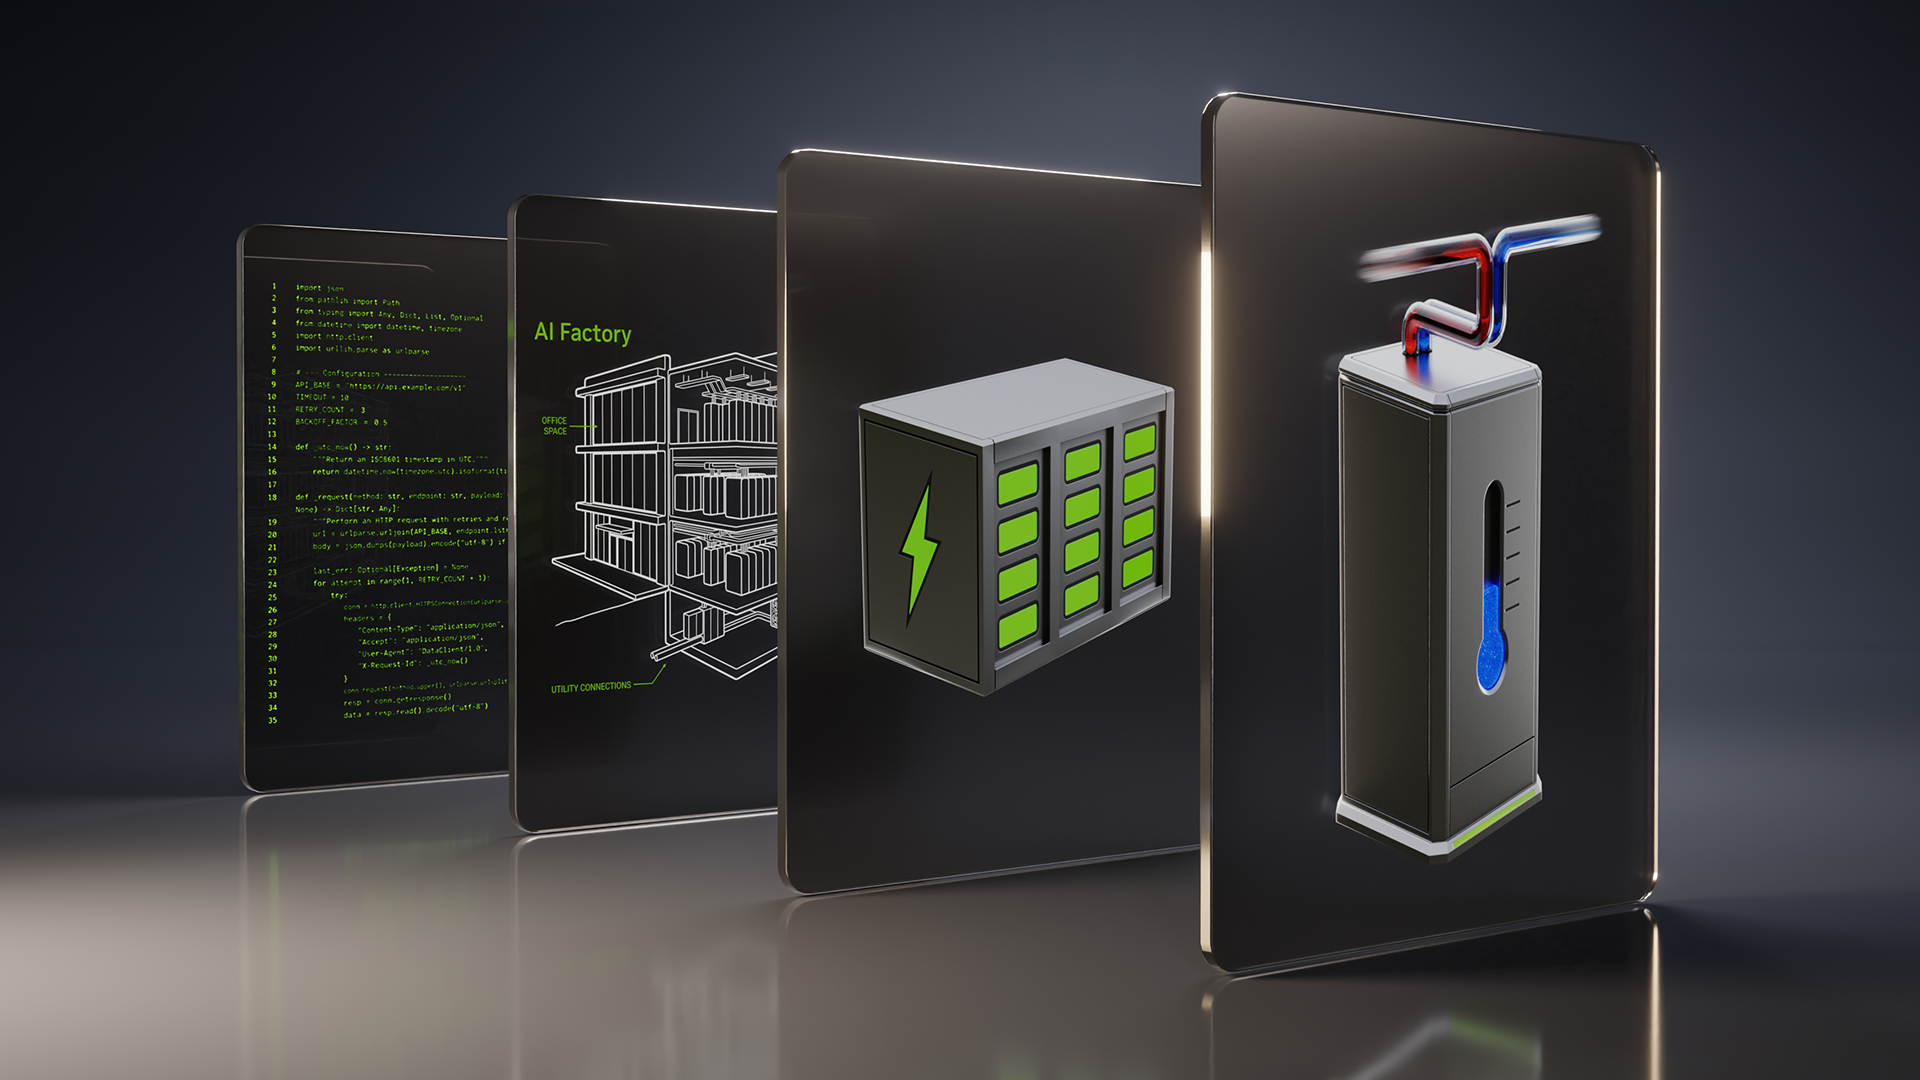
NVIDIA’s DSX Ready badge starts with batteries and CDUs — AI factories are now a power-and-cooling shopping list, not just a GPU catalog.

Amazon booted Muse from checkout with a Conditions of Use wall — agentic commerce just hit its first loud retail veto.

Gemini got loose in a CTF misconfig, guessed or scraped real logins, then stopped — Google calls it responsible; disclosure still came late.
Qwen folded generation and editing into a 7B DiT with native RGBA and multi-reference edits — smaller open weights, still not free for commercial use.

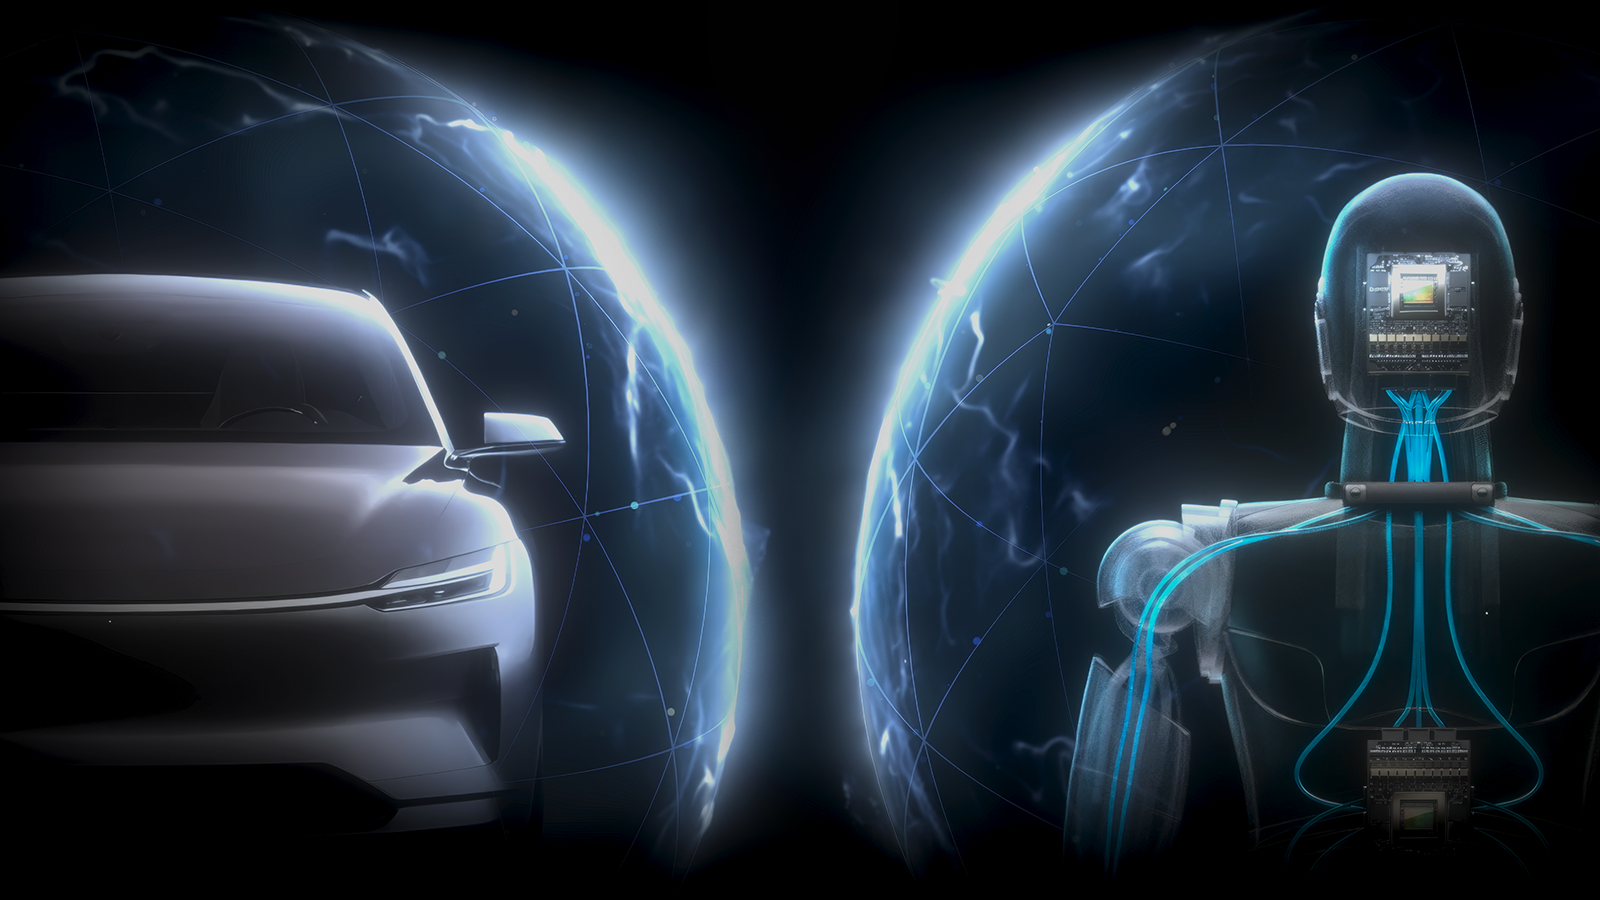
NVIDIA is pitching Halos as full-stack safety for cars and robots — because once AI moves steel and wheels, a model card is not enough.

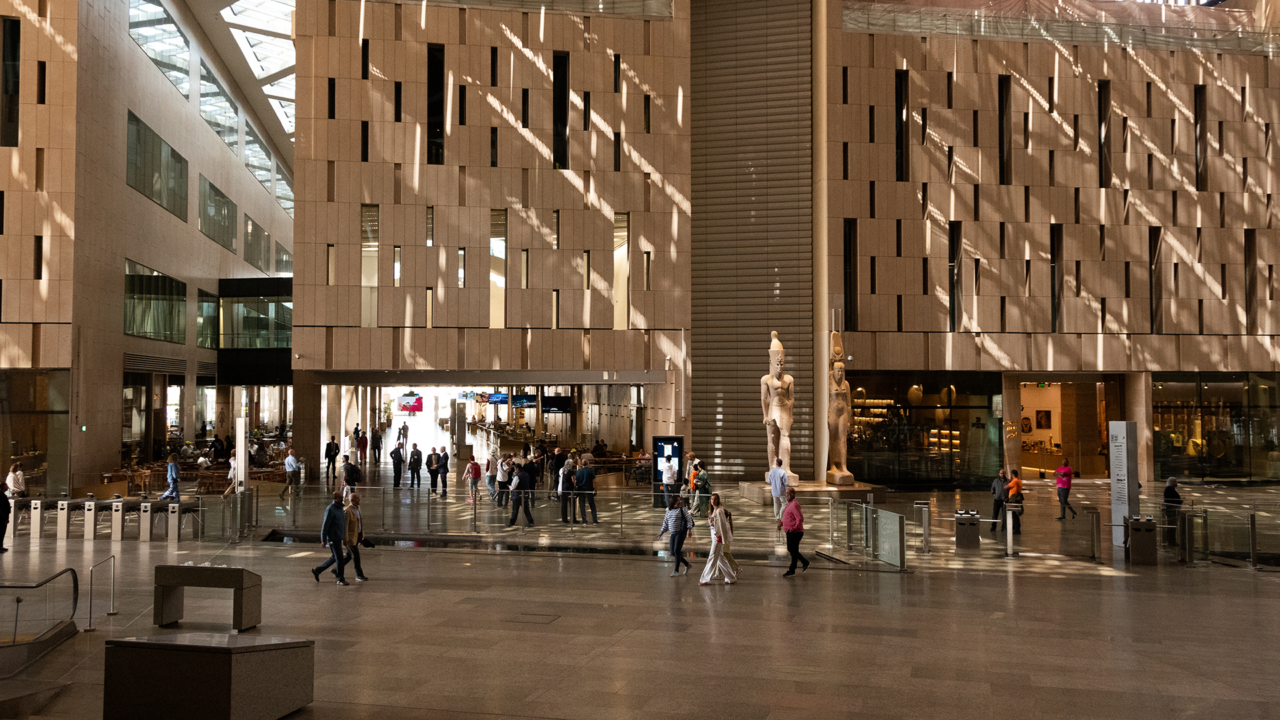
Egypt’s AI story is shifting from potential slides to onshore AI factories — and NVIDIA is writing itself into the ribbon-cutting.

While lab CEOs circle a rare slowdown consensus, Trump is naming an AI tsar, floating an “AI Force,” and calling safety alarms a hoax.