AI · Oct 28, 2026
RTX Spark laptops get open speech models and a dial for background agentsNvidia’s four-Spark ring is a pitch to scientists tired of waiting in the cluster queue
· Updated · Signal Desk newsroom
Analysis of reporting by NVIDIA Blog. How we work
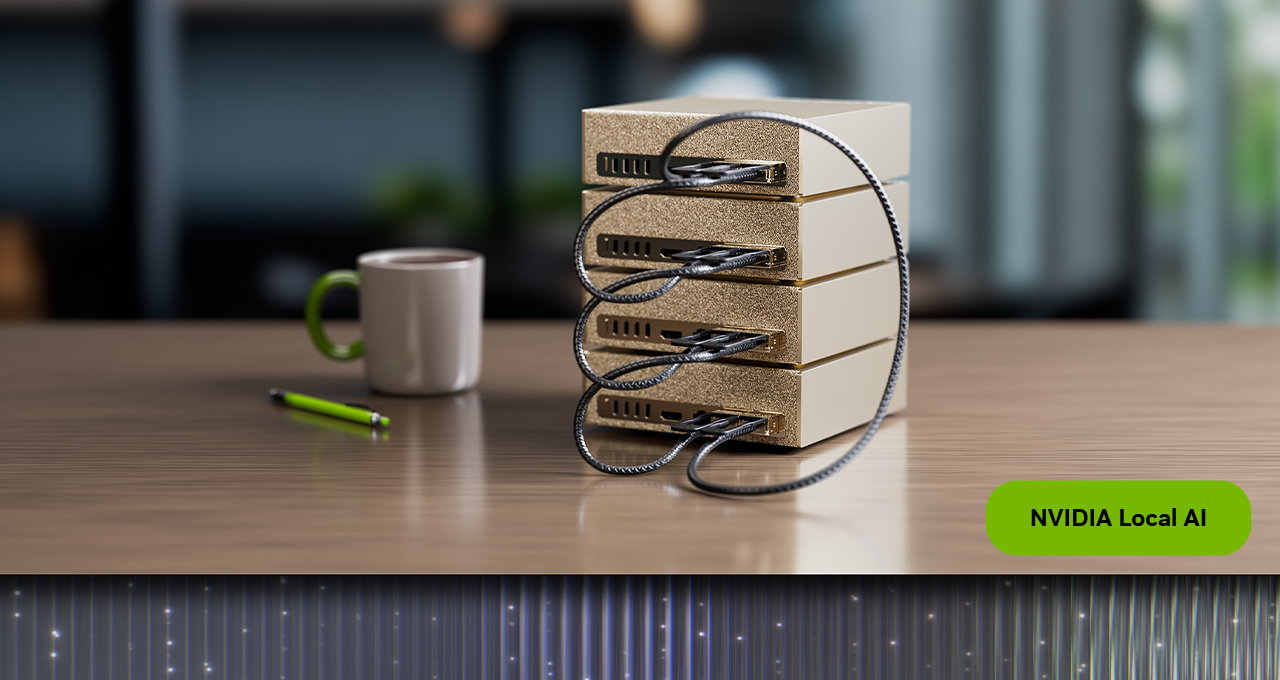
At SC26, Nvidia introduced a DGX Spark HPC Developer Kit that links four units in a switchless ring for 512GB of memory. The appeal is less raw power than independence from shared supercomputer queues.
Key takeaways
- The kit links four DGX Spark systems in a ring over ConnectX-7, with no network switch needed.
- At four nodes it offers 512GB of combined memory and 16TB of NVMe storage; with NVFP4, Nvidia says models up to 700B parameters can run locally.
- An NVIDIA HPC SDK playbook with C, C++ and Fortran compilers and MPI tools is coming soon.
- UC Berkeley labs report skipping 11-hour and multi-day cluster queues; one says results arrived 15x sooner.
- The kit is on sale now through OEM partners and NVIDIA Marketplace; Nvidia’s post lists no kit price.
The real product is time
Supercomputers are fast; getting onto them is slow. Researchers with fixed allocations queue for hours or days for jobs that are often just debugging runs. Nvidia’s DGX Spark HPC Developer Kit, introduced at SC26 in Chicago, targets that waste. It connects four DGX Spark systems, each with a GB10 Grace Blackwell Superchip, directly to their neighbors in a ring over ConnectX-7, with no switch to buy or configure. Fully built, it provides 512GB of combined memory and 16TB of NVMe storage.
Nvidia’s pitch is that teams can develop, debug and test multi-node code at their desks, save allocation hours for production runs and keep unpublished results and proprietary data on premises. That is a reasonable value proposition. Moving from one node to four is where distributed-computing bugs appear, and finding them on a desk instead of a shared machine is genuinely useful.
What runs on it
Nvidia says four-system demonstrations include LAMMPS with Kokkos for materials simulation and NAMD for molecular dynamics, while the broader community has validated GROMACS, OpenFOAM, WRF and NIM microservices like OpenFold3 and Boltz-2. With NVFP4 quantization, Nvidia says models up to 700B parameters, such as DeepSeek V4.1, can be deployed locally across the four nodes. New open data and post-training recipes for Nemotron 3.5 Super VL target life sciences and chemistry. The HPC SDK playbook, with GPU-accelerated C, C++ and Fortran compilers and MPI tools, is promised but not yet out.
This launch is part of Nvidia’s broader SC26 framing that science is entering the age of agents. Nvidia describes agent workflows that prepare simulation inputs, launch runs and summarize results while scientists validate setups and conclusions.
The evidence, mostly anecdotal
The user examples are specific and plausible. UC Berkeley’s Rubin Lab at IGI says it got results 15x sooner using Evo 2 on a DGX Spark because it skipped 11-hour cluster queues. That speedup is about waiting, not compute, which is exactly the point. Berkeley’s Hartwig Group says NVFP4 let it LoRA fine-tune a 120B-class Nemotron model on a single device and run eight- to 24-hour training fits back-to-back. Kvantify reports tensor-network simulations of quantum-chemistry circuits with up to 70 qubits and 975 gates on one Spark. CYRAN AI uses it to speed JPEG 2000 decoding of satellite imagery.
All of these come from Nvidia’s blog, and several involve a single unit rather than the four-node kit. The kit’s own performance claims are mainly about capacity. Researchers should also note the HPC tooling that makes multi-node development practical is still listed as coming soon.
Where it fits
Nvidia has been building out the Spark line quickly, from the 64GB DGX Spark to Windows-based RTX Spark desktops. This kit extends the line to scientific computing. For universities and research labs, the calculus is simple: if a few desk-side systems free up shared allocation for production science and speed up iteration, the purchase pays back in researcher time. The downside is fragmentation, with more compute scattered across labs rather than pooled, and dependence on Nvidia’s software stack for both local and cluster work.
Who benefits
- Academic researchers
- Local multi-node development without waiting in shared cluster queues.
- HPC centers
- Fewer debugging jobs on shared systems, potentially freeing time for production runs.
- Life sciences and chemistry labs
- On-premises fine-tuning and inference for sensitive or unpublished data.
- OEM partners
- A new SKU for Acer, ASUS, Dell, GIGABYTE, H3C, HP, Lenovo, MSI and xFusion.
What to watch
- Release of the NVIDIA HPC SDK playbook for the four-node cluster.
- Kit pricing from OEM partners compared with cluster allocation costs.
- Independent benchmarks of the ring topology on communication-heavy workloads.
- Adoption by university HPC centers as a sanctioned on-ramp to shared systems.
FAQ
What is the DGX Spark HPC Developer Kit?
A four-node cluster of DGX Spark systems linked in a switchless ring, giving 512GB of combined memory for scientific and AI workloads.
How large a model can it run?
Nvidia says up to 700B parameters with NVFP4 quantization across four nodes.
What scientific software works on it?
Nvidia cites LAMMPS, NAMD, GROMACS, OpenFOAM, WRF, OpenFold3 and Boltz-2; an HPC SDK playbook is coming soon.
Where can researchers buy it?
Through OEM partners and NVIDIA Marketplace; Nvidia’s announcement doesn’t list a price.
Companies: NVIDIA
More on NVIDIA
AI · Nov 5, 2026
NVIDIA’s four open Cosmos 3 Nano models let robot and driving teams simulate worlds that reactAI · Nov 16, 2026
Rubin HPC is Nvidia’s bet that science agents will be bottlenecked by simulation, not reasoningAI · Nov 9, 2026
Nvidia’s Korean startup bets span interconnect, open models, robot hands and document AIAI · Nov 8, 2026
Nvidia’s Dynamo recipes speed four Korean open models to production, tuned for B200s